Yuhao Ge
Inference @ Google | Previously: Compiler @ AWS Annapurna Labs | CS @ UIUC

I am an LLM serving and performance engineer with cross-accelerator expertise (TPU, Trainium, GPU). My work spans framework, compiler, and kernel optimization for large-scale serving systems.
At Google, I built vLLM-TorchTPU from the ground up and grew the team to over 50 people. I work closely with key customers and collaborate with Inferact and RadixArk on production adoption and optimization. My work spans initial design and bring-up, Pallas kernels, compiler/runtime co-design, and distributed serving features such as parallelism, quantization, and scheduling, together with model bring-up and performance hill climbing for production and SemiAnalysis AgentX submissions. I also co-develop TorchTPU and SGLang-TorchTPU as part of this open-source serving stack.
Previously, at AWS Annapurna Labs, I was a founding engineer of NKI, co-creating its domain-specific language and compiler for AWS Trainium chips. My work also included compiler optimizations, FlashAttention kernels, and autotuning infrastructure.
I earned an M.S. in Computer Science and a B.S. in Computer Engineering from UIUC, graduating with Highest Honors and Bronze Tablet recognition. Working with Prof. Charith Mendis, I co-authored SPLAT, a GPU code-generation framework for sparse attention published at OOPSLA 2025.
Earlier, I worked on ML-driven FPGA accelerator optimization at the UCLA VAST Lab with Prof. Jason Cong, and on real-time avatar animation systems at TikTok.
🎉 news
| Oct 20, 2026 | 🚀 Our PyTorch-native TPU serving stack is now open source: vLLM-TorchTPU, SGLang-TorchTPU, and TorchTPU. Read the launch announcement. |
|---|---|
| Nov 01, 2025 | I joined Google as a Software Engineer. I now lead development of the PyTorch-native vLLM TPU backend and work across the TPU serving stack, TorchTPU, Pallas kernels, model optimization, and quantization. |
| Apr 09, 2025 | 🚀 Our paper, “SPLAT: A Framework for Optimised GPU Code-Generation for SParse reguLar ATtention”, has been accepted at OOPSLA 2025. |
| Mar 01, 2025 | I joined Amazon AWS, Annapurna Labs, as a software engineer. |
| Aug 09, 2024 | I received a Certificate of Appreciation from the Neuron Compiler team at Amazon Annapurna Labs for developing autotuning infrastructure that significantly improved AWS Trainium performance. This project was recognized as one of the most impactful contributions during my internship. |
💼 work
| Google Software Engineer | 2025 – Present |
| AWS, Annapurna Labs Software Engineer | 2025 |
| AWS, Annapurna Labs Software Engineer Intern | 2024 |
| TikTok Software Engineer Intern | 2022 |
| University of California, Los Angeles Research Assistant | 2022 |
🎓 education
| University of Illinois at Urbana-Champaign (UIUC) M.S. in Computer Science | 2023.8 - 2024.12 |
| University of Illinois at Urbana-Champaign (UIUC) B.S. in Computer Engineering | 2019.8 - 2023.5 |
📝 selected papers
- OOPSLA 2025
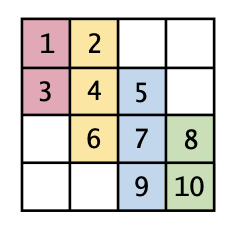 SPLAT: A Framework for Optimised GPU Code-Generation for SParse ReguLar ATtentionAhan Gupta, Yueming Yuan, Devansh Jain, Yuhao Ge, David Aponte, Yanqi Zhou, Charith MendisWe introduced the Affine Compressed Sparse-Row (ACSR) format and the SPLAT code-generation framework for regular sparse attention, achieving 2.05x and 4.05x speedups over Triton and TVM.

🥁 drumming
Drumming has been a consistent passion in my life, helping me maintain creativity and rhythm in everything I do. Check out my videos here, or visit my YouTube and Bilibili channels.